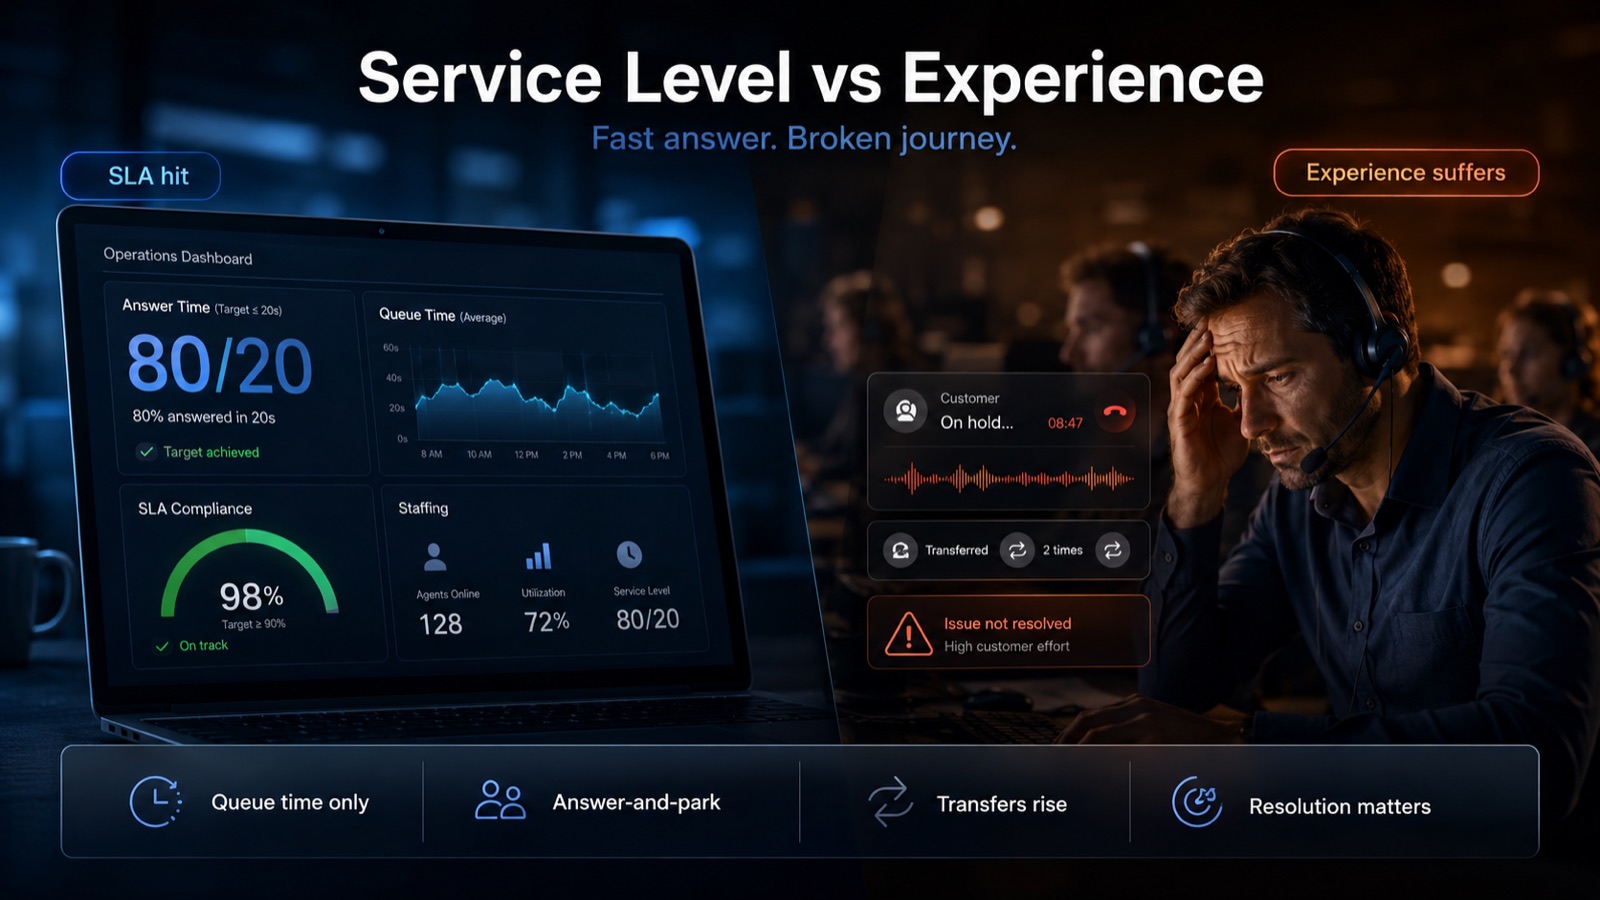
Call center service level is the share of contacts answered within a target time, written as X/Y: 80/20 means 80% of calls answered within 20 seconds. It is a good measure of one situation, a customer waiting on a live line, and a poor measure of everything else. Yet it often ends up on the scorecard for email, messaging and web forms too, where nobody is waiting on a line at all.
This guide covers what service level measures, how to calculate it, what a good target is and where 80/20 came from. Then it shows how to split your targets in two: live contacts measured in seconds, asynchronous contacts measured by substantive replies, resolution and repeat contact. It ends with a six-week rollout and a checklist. Everything is also in a free seven-page PDF, the async SLA one-pager and toolkit, with a SQL template for the analysis.
What is service level in a call center?
Service level is the percentage of contacts answered within a threshold you choose: X% within Y seconds. It measures how long customers wait before an agent picks up, which is why it always travels with abandonment. A caller who hangs up before the threshold never appears in the answered count, so a service level reported without its abandonment rate can look healthy while the queue is losing customers.
The metric belongs to contacts that have to be handled when they arrive: phone calls, live chat, video. ICMI's guide to contact center metrics splits contacts in two: service level (X% answered in Y seconds) for contacts that must be handled when they arrive, and response time (100% answered within N minutes, hours or days) for contacts that can be handled later, such as email, deferred social media and call-me-later requests. The guide files web chat and SMS on the service-level side. The split is decades old; it was already in ICMI's 2003 metrics tutorial. What changed is that email, chat and messaging now land in the same operation, often on the same scorecard, and the second clock is easy to lose there.
How is service level calculated in a call center?
The basic call center service level formula divides the contacts answered within the threshold by the contacts offered. The disagreement is over abandoned calls, and the common versions give different results for the same interval.
Take one 30-minute interval: 1,000 calls offered; 800 answered within 20 seconds, 120 answered later, 30 abandoned within 20 seconds and 50 abandoned after 20 seconds.
| Formula | What it does with abandoned calls | Result |
|---|---|---|
| Answered within Y ÷ offered | Counts every abandoned call as a miss | 80.0% |
| Answered within Y ÷ (offered − abandoned within Y) | Leaves out callers who gave up before the threshold | 82.5% |
| (Answered within Y + abandoned within Y) ÷ offered | Counts early abandons as met | 83.0% |
| Answered within Y ÷ answered | Leaves out every abandoned call | 87.0% |
Same customers, same waits: 80% to 87%, depending on the formula. Pick one, write it down, apply it to every queue and every outsourcing partner, and never compare numbers calculated differently. If you also exclude very short abandons, such as callers who hang up in the first five seconds, put the cutoff in the written definition.
Calculate service level per 15- or 30-minute interval, not only per day. A daily 80% can be a morning at 60% and an afternoon at 95%, and the morning's customers never experienced 80%.
What is a good service level for a call center?
There is no universal good number. ICMI's own research report puts it plainly: outside utilities and other regulated industries, "there is generally no 'industry standard' service level for contact centers." In that 2011 survey of 428 contact center professionals, 22.6% said their organizations used 80/20 as the industry standard, and only a little over 10% based their service level on customer expectations. ICMI's metrics guide lists 80/20 as one "moderate" example among objectives that run from 90/15 to 80/300, and nobody seems to know where 80/20 came from. It spread because it is easy to measure and easy to copy into the next contract, not because anyone showed that customers stop being satisfied in the 21st second.
A good service level is one you derived from your own customers and priced before you promised it:
- Choose Y from your abandonment curve. Take 90 days of calls and plot the share of callers who abandoned against how long they had waited. The curve is usually flat for a while, then bends upward. That bend is your customers' patience; put Y before it.
- Choose X from the cost of each point. In an Erlang C staffing model, each extra point of service level costs more agents than the one before. Price the step from 80% to 90% in agents and payroll before you commit to it.
- Give different lines different targets. A lost-card line and a billing-question line do not share a patience curve.
Then use it only for live contacts. Everything else needs a second clock.
Why 80/20 breaks on email and messaging
An email or a WhatsApp message has no line to wait on. The customer sends it and gets on with their day; your reply arrives as a notification. Putting that contact on a clock measured in seconds breaks three things.
It measures a wait nobody experiences. Whether a message is answered in 19 seconds or 19 minutes, the customer is usually not looking. What they experience is whether the answer, when it comes, solves the problem, and whether they have to write again.
It rewards the fastest possible non-answer. A clock that stops on any reply is stopped by an auto-acknowledgment or a "looking into it" message. The wallboard turns green, the customer is still waiting, and first response time improves while resolution does not.
It staffs async queues like phones. Keeping email or messaging agents free to pick up a message within seconds is expensive, and it buys a kind of speed customers measure differently. Customers do want fast answers, but for a message, fast means minutes to an hour: in Toister Performance Solutions' 2020 survey, replying within an hour met the email expectations of 88% of consumers. What drives customers away is having to come back. In the research behind Harvard Business Review's "Stop Trying to Delight Your Customers", 62% of customers reported having to contact the company repeatedly to resolve an issue, and the authors found that nothing adds more customer effort than having to call back. That is the case for tracking first call resolution and repeat contact next to any speed target.
Voice queues have their own version of the problem when service level is the only number that counts; this piece on service level agreements covers it.
Synchronous or asynchronous? The wait-state test
Classify every queue by the customer's wait state, not by the channel's name. Ask one question: while you haven't replied, is the customer stuck in the conversation, unable to do anything else?
| Contact | While you haven't replied, the customer… | Clock |
|---|---|---|
| Phone or video call in a queue | is on the line and can't do anything else | Live |
| Live chat, window open | watches the window | Live |
| Chat after the customer leaves | will read your reply later | Async |
| Messaging: WhatsApp, SMS, in-app | gets a notification and carries on | Async, unless both sides are typing |
| Email, web form, social DM | expects a reply later | Async |
| Scheduled callback | was promised a time | Async, against the promised time |
Two edge cases matter in practice. A messaging conversation can turn live when both sides are typing: keep the queue on the async clock and track the reply gap inside the conversation separately. And a platform can set the ceiling for you. On WhatsApp, each customer message opens or resets a 24-hour customer service window; once it closes, a business can send only pre-approved template messages. An async target longer than that fails on WhatsApp by design.
What to measure on the async clock
An async service level keeps the familiar shape, X% within a threshold, but runs on business hours and travels with different companions:
| Measure | Definition | Target form |
|---|---|---|
| Substantive reply time | From the customer's message to the first reply that answers, resolves or asks for information you need. Auto-replies and holding messages don't count. | X% within N business hours |
| Time to resolution | From the first message to the fix, excluding time spent waiting on the customer | P90 per topic family |
| Repeat contact rate | Resolved conversations followed by a new contact from the same customer within 72 hours, on any channel | Guardrail: must not rise |
| Oldest waiting conversation | Age of the oldest conversation without a substantive reply | Wallboard alarm at N hours |
Most async SLAs fail on definitions, not on targets. ICMI's guide already separates three events: the automatic reply that confirms receipt and says when to expect an answer, the agent's response that response time measures, and the resolution. These clock rules put that separation into your helpdesk:
- Start at arrival: when the customer's message lands, not when someone picks it up.
- Stop on substance: a reply that answers, resolves or asks for information you need to proceed.
- Auto-replies never stop the clock. Keep them to set expectations ("We reply within 4 business hours. Lost card? Call us now."), just don't count them.
- Pause only on the customer: from the moment you ask them for something until they answer.
- Chasers don't reset the clock. "Any update?" means it already ran too long.
- Resolved means solved, not closed. A new contact about the same issue within 72 hours reopens it.
- Report percentiles, not averages. P90 shows the conversations that waited two days; an average hides them.
Before you trust the number, check what your helpdesk's timer already does with automated messages. Some platforms leave automated replies out of first reply time by default; others let an automated public note stop the timer, or leave the definition of "first response" to whoever configured it. Test it: send a message, let the auto-reply fire, and see whether the clock stopped.
The 30-day test: does reply time predict repeat contact?
Before you choose N, find out whether reply speed changes what customers do next. You need two exports: resolved async conversations with their first substantive reply time, and every new contact from the same customers, on every channel.
- Take conversations resolved between 33 and 3 days ago, so each one has a full 72-hour window after it.
- Flag a repeat when the same customer made a new contact, calls included, within 72 hours of resolution. A "thanks!" in the same thread is not a new contact.
- Bucket the first substantive reply time: under 15 minutes, 15–60 minutes, then 1–2, 2–4, 4–8, 8–24 and over 24 hours.
- Chart the repeat rate per bucket, with the number of conversations beside each bar. Ignore buckets with fewer than a hundred or so conversations.
- Do it again per topic. Hard problems get slower replies and more repeats, so an all-topics curve can show the mix of work rather than the effect of speed.
Why 72 hours? It catches the fast failures and fits the test into 33 days of data. The HBR authors recommended tracking repeat calls over seven to 14 days, so run a 7-day version as well if your issues surface slowly, as billing and claims often do.
Look for two shapes. Flat: repeat contact barely moves with reply time, so speed is not the lever in that range. Keep a target customers find reasonable and put the effort into resolution. Knee: repeats hold steady, then climb past a point. Set N just before it. And if repeats are highest in the fastest bucket, read those conversations; fast replies may be templates that don't solve anything.
Run the test twice more: with time to resolution on the x-axis, and with CSAT or DSAT on the y-axis if you survey customers. The PDF has the SQL for all of it and a spreadsheet method for teams without a data warehouse.
The slow part is usually the topic. If the contact reasons in your helpdesk are unreliable, conversation analytics can supply them: in Ender Turing, topics group conversations into themes using generative AI, rules or human labeling, and feed filters, dashboards and charts. It is part of what contact center operations look like when every conversation is analyzed rather than sampled.
How to set live and async targets
A target is a promise with a cost. Derive each number from your own data and write down how it is calculated.
Live contacts: Y from your abandonment curve, X from the price of each extra point, measured per interval with one written formula.
Async contacts:
- N is the earliest of three limits: the knee from the 30-day test, the reply time you publish to customers, and platform rules such as WhatsApp's 24 hours.
- X sits at P90 or P95, not 100%, with a backstop: no conversation waits longer than twice N.
- The guardrail is repeat contact within 72 hours, which must not rise when you change N.
- Resolution gets its own P90 target per topic family, not one number for everything.
Staffing follows the clock. Size live work per interval with Erlang C or a simulation. For work that can wait, ICMI's tutorial points to workload methods instead, and back to queuing math only when response targets drop below about an hour. For async work, size capacity by workload inside the window: agent hours per day equal conversations × handle time ÷ target occupancy, where handle time is all the agent time a conversation takes across every reply. Then schedule so that the work due in the next N hours never exceeds the capacity in those hours, route by due time rather than arrival order, and let async work fill the quiet hours of live demand.
What is a service level agreement in a call center?
A service level agreement is the written commitment behind the numbers: to customers, between departments or with an outsourcing partner. In a call center it names the service level target, how it is measured and what happens when it is missed. A service level agreement for call center outsourcing is where the single-clock problem gets expensive, because the vendor is paid to hit the number in the contract, and an auto-reply can hit it.
If your contracts set 80/20 across every channel, four clauses close the biggest gaps:
- Service level applies to live contacts only and is measured per 30-minute interval, with the formula in an annex.
- For asynchronous contacts, a response is a reply that answers the request, resolves it or asks the customer for information needed to proceed. Automated acknowledgments and holding messages are not responses.
- A conversation is resolved when the customer's request is fulfilled. A new contact from the same customer about the same request within 72 hours reopens it.
- Repeat contact within 72 hours is reported monthly per queue and may not exceed an agreed baseline.
This is sample wording; have your counsel adapt it to your contract.
A six-week rollout
- Week 1, classify. List every queue and entry point, tag each live or async with the wait-state test, and record where each current target came from.
- Week 2, fix the clock. Configure the clock rules in your helpdesk and contact-center platform: business-hours calendars, auto-reply exclusion, the pending-customer pause, the 72-hour reopen.
- Week 3, run the 30-day test per channel and topic, with the resolution-time and CSAT views.
- Week 4, set targets. Live Y and X from the abandonment curve; async N and X from the knee, your promise and platform limits; guardrails for both.
- Week 5, staff and route. Workforce models for both clocks, deadline routing, concurrency caps for messaging and a backlog plan.
- Week 6, report and contract. Separate scorecards and wallboards, reply-time promises on channel pages and auto-replies, rewritten outsourcing SLAs and a quarterly review.
Checklist
- Every queue is tagged live or async by the wait-state test.
- Auto-replies and holding messages are excluded from response time.
- The clock starts at arrival and pauses only while you wait on the customer.
- A repeat contact within 72 hours reopens resolution.
- Live Y comes from your own abandonment curve, with one written formula.
- Async N comes from the 30-day test, your published promise and platform limits.
- Targets sit at P90 or P95, with a backstop at twice N.
- Repeat contact is tracked on every async queue.
- Live and async results sit on separate scorecards; there is no blended service level.
- The oldest waiting conversation is on the wallboard.
- The 30-day test runs again every quarter.
Service level asks the right question for a caller on hold, even if your own patience curve should set the answer. For the customers who write to you, it asks the wrong one. Give them a clock of their own, and measure what they came for: an answer that means they don't have to write again. Download the async SLA one-pager and toolkit (PDF) to take the rules, the target card and the SQL to your next planning meeting.